MoonRouter — Smart Multi-API LLM Proxy & Model Rotation System
A self-healing, multi-provider LLM gateway that hides 4 free AI providers behind one OpenAI-compatible endpoint — with automatic failover, API-key rotation, health-aware cooldowns and zero-downtime model swaps.
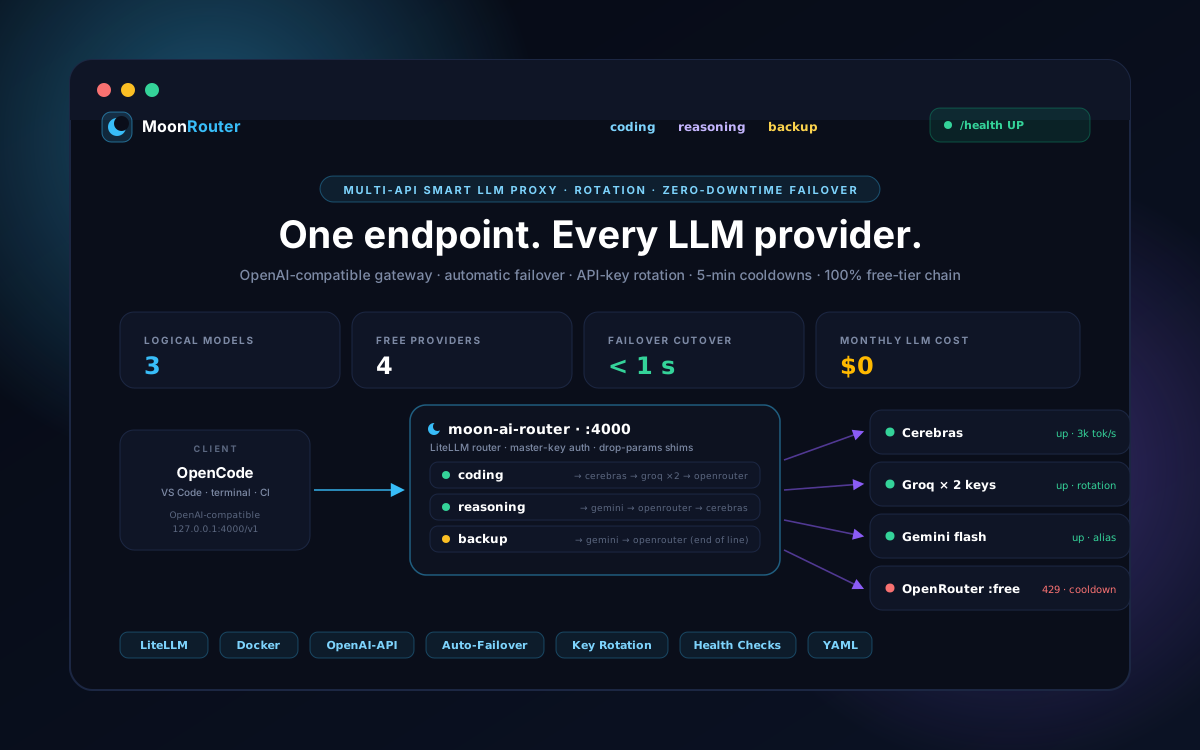
Project Overview
MoonRouter is a production-grade smart LLM proxy built on LiteLLM that turns a zoo of AI providers into one stable, OpenAI-compatible endpoint. Coding agents like OpenCode (and any OpenAI SDK client) see just three logical models — coding, reasoning, backup — while the router decides, per request, which real provider serves them: Cerebras, Groq (dual-key rotation), Google Gemini or OpenRouter free-tier models.
The system is engineered for resilience: a failed deployment is retried once, then skipped; two consecutive failures put a provider into a 5-minute cooldown so rate-limited or dead endpoints are never hammered. Context-window pre-call checks reroute oversized prompts to bigger-context models, per-deployment max_output_tokens clamp runaway client requests, and RPM caps protect free-tier quotas. Failover chains (coding → reasoning → backup) guarantee an answer as long as any provider is alive.
Operations are deliberately boring: a single declarative YAML file defines every deployment, key and failover rule; Docker Compose runs the router as a healthy-checked container bound to 127.0.0.1 with the master key and secrets injected via environment; a documented 10-step runbook covers port, health, models, keys and routing diagnostics. When a provider deprecates a model, one config edit and a container restart swaps it — clients never notice.
Key Contributions
Features
Have an idea? Let's build something extraordinary.
From full stack products to DevOps automation and AI-powered features — I'm available for freelance projects and full-time roles. Let's turn your vision into production software.